agentic-pipelines documentation
agentic-pipelines is an engine for pipelines that run unattended. You declare a pipeline in YAML as a graph of steps: plain shell steps, and agent steps that hand the work to an AI agent (through the Claude Agent SDK) inside a filesystem sandbox that the engine itself enforces, not the SDK. launchd on macOS, or a systemd user timer on Linux, fires each pipeline on schedule; the engine runs it, stores every run on disk and notifies you when it finishes.
The engine ships no pipelines of its own. Yours live in a separate data repo that you create, and the engine finds it at run time by locating its pipelines.yaml. If you'd rather start from something that already works, pipelines-starter has seven ready-to-use pipelines.
Status. Version 0.1.0. It runs on macOS (scheduled with launchd) and on Linux with systemd (scheduled with user timers). There is no crontab backend, and Windows through WSL2 hasn't been verified.
How it fits together
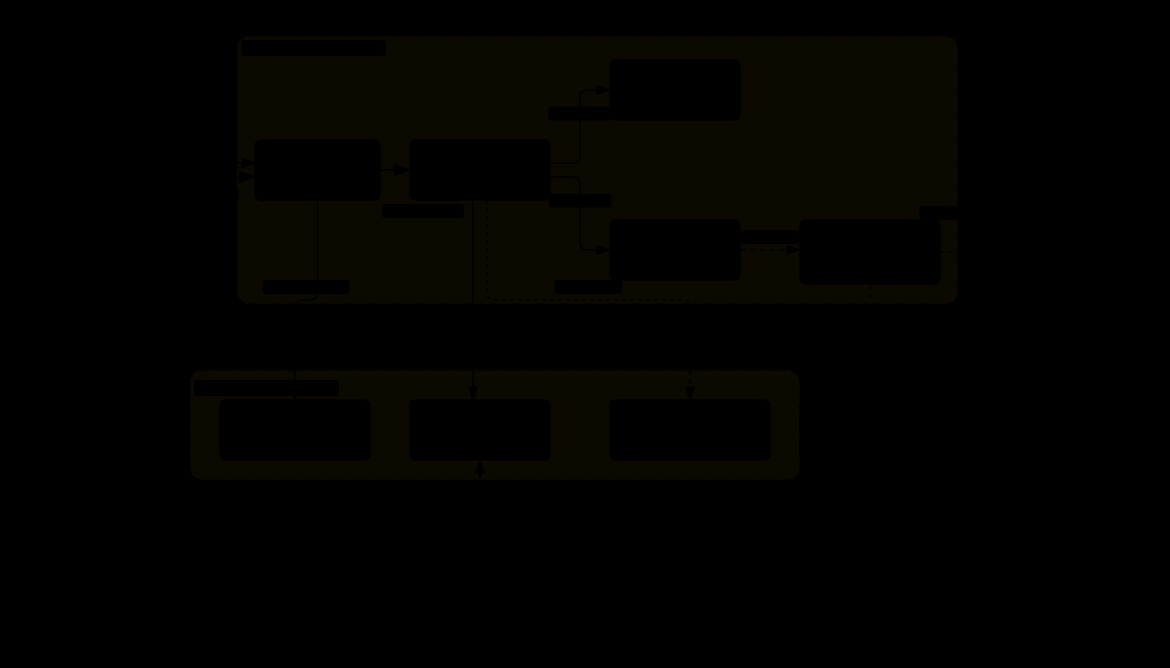
Three separate places are involved, and it pays to keep them apart in your head:
| Place | What it holds | Who changes it |
|---|---|---|
| The engine | Schema, runner, CLI, filesystem guard, linter | Whoever adds a capability to the engine |
| The data repo (yours) | One directory per pipeline with its pipeline.yaml, the prompts for its agent steps, the agents, and the notification channel scripts | Whoever adds or changes a pipeline |
| Outside both | The launchd plists or systemd units, each pipeline's workspaces, the .runs/ history | The engine, when installing and running |
The third one is what you won't see by reading code, and it's where to look when something doesn't add up. What lives on disk lists every path.
The engine assumes nothing about what a pipeline does: it only knows how to execute the contract that pipeline.yaml describes. Each step declares its inputs and outputs, the engine builds the graph, validates every output against its contract before passing it to the next step, and a set of guards decides whether the run starts at all.
What happens during a run
- Trigger.
launchdor thesystemdtimer at the cron time, or someone runningpipelines run. - Preflight. Three checks, in this order:
requireschecks whether this machine can run the pipeline (binaries, agents, secrets, network). If anything is missing, the run fails.- The per-pipeline lock. If a run is already in progress, the command exits with code 3.
- The
whenguards check whether today is the day (throttle,changed,shell,between). If any of them doesn't pass, the run ends asskipped, with exit code 0. That's not an error: it's the normal outcome on half the nights of a pipeline with athrottle.
- Steps. In the order the graph dictates. A
shellstep runs withsh -c(bash --posix -con Linux) in a narrow, fixed environment; anagentstep opens a governed session (see Agent steps and the sandbox). A step withoutputs:must write exactly the JSON of its contract to stdout. - Wrap-up. The steps under
always:run every time, on success or failure. Then thenotifychannel receives the result, ifnotify.onincludes it or if the pipeline has gone too long without a success (stale_after). - Result. A
successanchors thethrottleof the next run. Afailedrun stores the last lines of the failing step's stderr in that step'serror, and can be resumed withpipelines resume.
Everything lands in .runs/<pipeline>/<run-id>/ inside the data repo: a run.json with the full record and one log per step, with secrets already redacted.
Where to go next
- Install on macOS or Install on Linux.
- Your first pipeline: a shell-only pipeline, then one with an agent step, checked against the real CLI.
- The pipeline.yaml reference for every field, and Commands for every command and exit code.
Known limitations
- There is no
pipelines init. Creating a new data repo (itspipelines.yaml,agents/,.env) is still manual. - launchd and systemd only.
installanduninstallknow nothing about crontab or other schedulers. Windows through WSL2 hasn't been verified. - stdio MCP servers only. SSE and HTTP are not supported.
kind: playwrightorkind: declaredinmcp_servers.playwrightuses the engine's governance table.declaredis for a server of your own whose tools the engine doesn't know: you list what's allowed inallowand vouch that none of those tools runs arbitrary code or writes where it shouldn't.- No dependency cache between runs. The engine doesn't install a target repo's dependencies (a
yarn install, for example); preparing each environment is up to whoever prepares it.
